MCP Setup & Usage Guide
In this article
In this article group
Contents
Overview
The Dewey MCP server is a Model Context Protocol (MCP) integration that securely connects AI assistants to the Dewey Platform, allowing you to navigate the data catalog within Claude, ChatGPT, or other AI environments. Once connected, your AI assistant can search datasets based on your research question, topic, or theme; it can also explore schemas and documentation, preview sample data, retrieve download details, plan out analyses, and pull dataset citations.
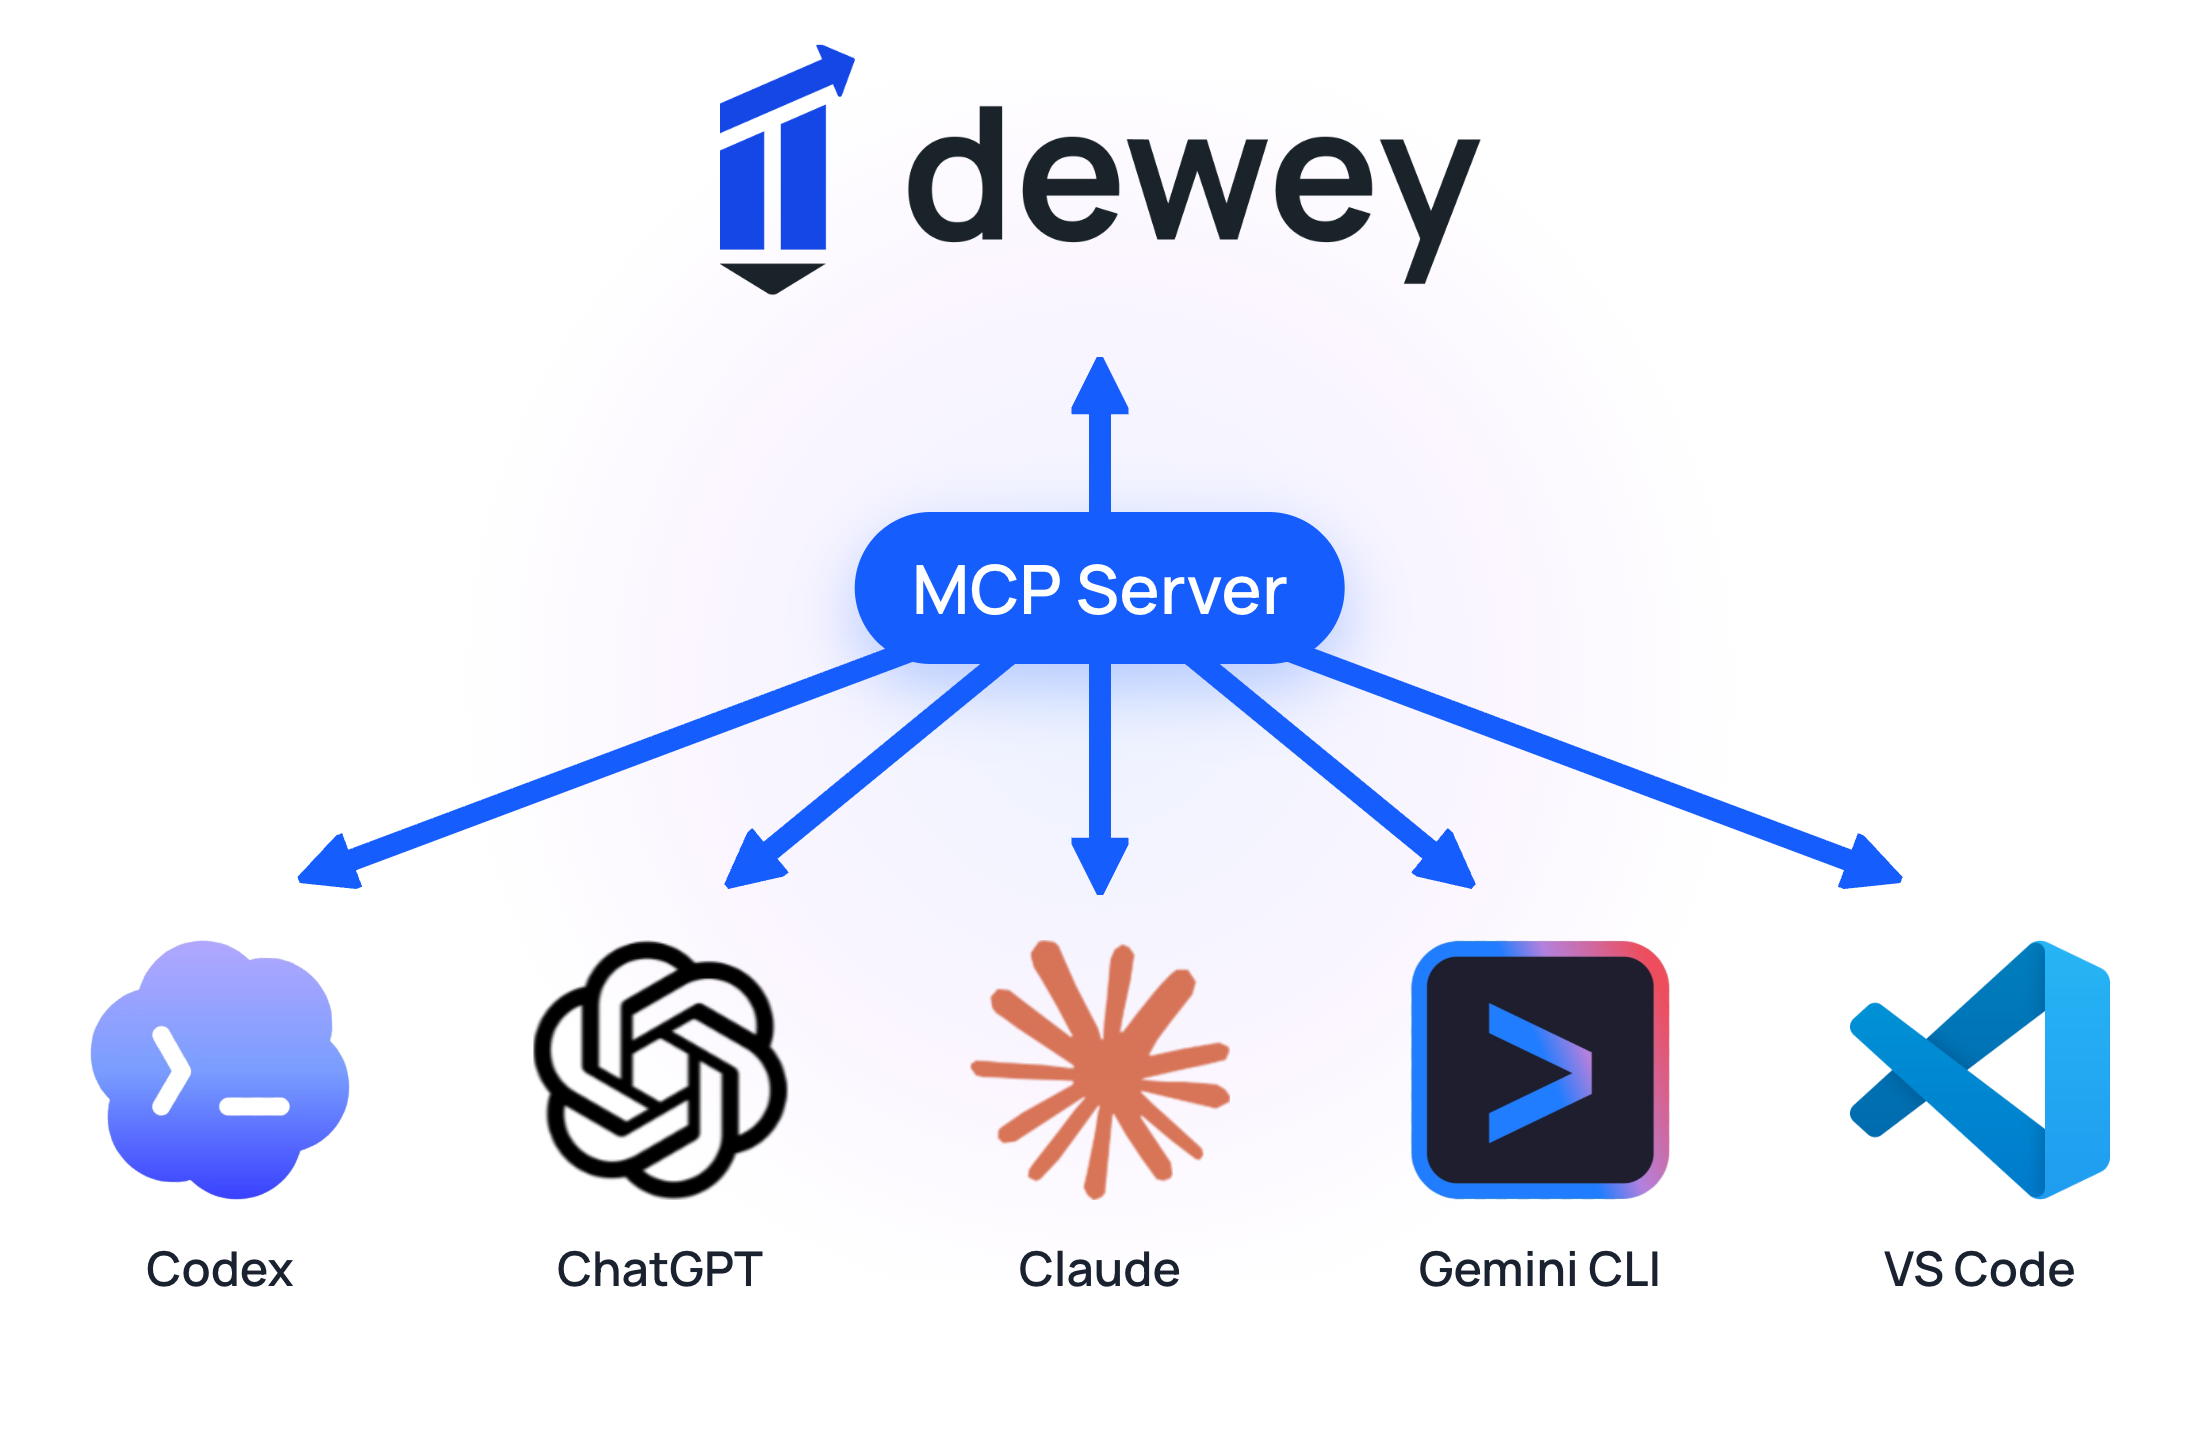
From discovery to evaluation to analysis, the MCP integrates dataset-level details into where you already work.
Before you start
You need a Dewey account. The MCP only shows datasets your account can access.
Claude or OpenAI tools: simply connect with One-Click Connection.
Manual installs: connect using your API key and code prompts below.
1. Get your API key: open a Project, click Get Data > Bulk API, and copy the key (or click Issue a New Key).
2. Save it as
DEWEY_API_KEY(see below), then restart your AI tool.
⭐️ Pro tip: save your API Key as a persistent environment variable for permanent re-use.
Save your API Key
Copy/paste code below, or for other options & detailed explanations, see guide here.
macOS (zsh, the default since 2019):
echo 'export DEWEY_API_KEY="YOUR_ACTUAL_API_KEY"' >> ~/.zshrc
source ~/.zshrc
echo $DEWEY_API_KEY   # verify
Linux (bash): same as above, but with ~/.bashrc in place of ~/.zshrc.
Windows (Command Prompt or PowerShell):
setx DEWEY_API_KEY "YOUR_ACTUAL_API_KEY"
Then open a new terminal to verify. setx doesn’t affect the window it ran in.
Command Prompt:
echo %DEWEY_API_KEY%PowerShell:
echo $env:DEWEY_API_KEY
🔗 How to Connect the MCP
➡️ One-Click Connection
Dewey has set up integrations with the app stores for Anthropic and OpenAI. All you need to do is add the Dewey Data Connector/Plugin and authenticate by signing in with your Dewey account login. One connection covers all of that company's tools.
Claude (Chat, Code & Cowork)
Go to Settings > Connectors and click Browse connectors.
Find Dewey Data, click Connect, and sign in with your Dewey account.
In a chat, make sure Dewey is turned on in the + menu.
Team or Enterprise plan: an Owner must enable Dewey for your organization first.
Mobile: connect on web or desktop; Dewey then works in the mobile app.
Claude Code and Cowork: sign in with the same Claude account and Dewey is already there. In Claude Code, type
/mcpto authenticate it if prompted.
Source: Anthropic help center
ChatGPT & Codex
Open the Dewey Data app, or go to Settings > Apps.
Click Connect and sign in with your Dewey account.
In a chat, type @ and pick Dewey, or choose it from the + menu.
Business, Enterprise, or Edu workspace: your admin controls which apps are on. Apps are off by default on Enterprise and Edu, so ask your admin to enable Dewey.
Codex: sign in to Codex with the same ChatGPT account and Dewey is available there too.
Source: OpenAI help center
🔁 Manual Installs
For any other AI tool, chatbot, or coding agent, follow this framework. Each install points to the Server URL and sends your key in an X-API-KEY Header.
Setting | Value |
|---|---|
Server URL |
|
Transport | Streamable HTTP |
Header |
|
Steps:
Open your tool's MCP settings or config file. It may be called MCP servers, connectors, or tools (see chart below).
Add a remote server with the Server URL.
Add an
X-API-KEYHeader with your API key. If the tool supports environment variables, useDEWEY_API_KEY. (Note: some tools may open a Dewey sign-in page instead).Restart the tool and run the check below.
Where the config goes
Tool | Where to add Dewey |
|---|---|
OpenAI Codex |
|
Claude Code |
|
Cursor |
|
GitHub Copilot (VS Code) |
|
Gemini CLI |
|
⚙️ Worked Example: Gemini CLI
Option A: run the command or edit the config yourself.
Option B: paste a prompt and let the AI tool set itself up.
Option A. In your terminal, then restart Gemini CLI and type /mcp:
gemini mcp add --transport http --scope user \
  --header 'X-API-KEY: $DEWEY_API_KEY' \
  dewey https://api.deweydata.io/mcp
Single quotes keep your key out of the file; Gemini CLI reads DEWEY_API_KEY each time it starts. On Windows, use the settings.json option below instead.
Or add to ~/.gemini/settings.json:
{
  "mcpServers": {
    "dewey": {
      "httpUrl": "https://api.deweydata.io/mcp",
      "headers": { "X-API-KEY": "$DEWEY_API_KEY" }
    }
  }
}
Option B. Paste into Gemini CLI:
Add the Dewey MCP server to ~/.gemini/settings.json. Create the file if needed, keep existing settings, and add this under "mcpServers". My API key is in the DEWEY_API_KEY environment variable; don't ask me for it or write it into the file.

"dewey": {
  "httpUrl": "https://api.deweydata.io/mcp",
  "headers": { "X-API-KEY": "$DEWEY_API_KEY" }
}
Tool only supports local servers? Use mcp-remote as a bridge (requires Node.js):
{
  "mcpServers": {
    "dewey": {
      "command": "npx",
      "args": ["mcp-remote", "https://api.deweydata.io/mcp", "--header", "X-API-KEY:${DEWEY_API_KEY}"],
      "env": { "DEWEY_API_KEY": "YOUR_API_KEY" }
    }
  }
}
☑ Check that it works
Ask: "What Dewey datasets do I have access to?" You should get a count of datasets with options to explore by topic, data provider, category, etc. If the AI answers from general knowledge instead, see Troubleshooting.
🔑 MCP Usage Guide
Best practices and getting the most out of your Dewey MCP
🛠️ Available tools
Know what functions are pre-baked into the MCP. Your AI tool selects and calls them automatically based on what you ask, so you don't need to name them.
Tool | What it returns |
|---|---|
| Datasets matching keywords. Filter by category, data partner, data product, region, or sample and download access. |
| Datasets ranked by meaning, for questions like "foot traffic near retail stores" |
| Categories you can access, with dataset counts |
| Data partners and their data products, with dataset counts |
| Description, coverage, refresh schedule, file type and size, your access, and the DOI with a ready-to-paste citation |
| Columns, types, descriptions, and partition info |
| Companion tables, other datasets in the same data product, and joinable datasets |
| Links to the partner's and the dataset's documentation |
| Link to a data partner's documentation |
| Download permissions, file type, size and row estimates, date partitions, customization requirements, and partner download terms |
| Sample rows as JSON or CSV, for the columns you choose |
Note: these tools are read-only. To download data, see Data Access.
💬 Example prompts
Use the MCP at each stage of the research data workflow: discover datasets, evaluate whether one fits, then plan your download and analysis.
Discover data
Find candidate datasets for your research question.
Task | Example prompt |
|---|---|
Search by topic | "Which Dewey datasets cover US job postings since 2015?" |
Browse your access | "Which real estate datasets can I download?" |
Find related data | "What other datasets could I join with [dataset]?" |
Evaluate a dataset
Decide whether a dataset fits before you download it.
Task | Example prompt |
|---|---|
Compare datasets | "Compare the coverage and refresh schedule of these two datasets." |
Review the schema | "Show the schema for [dataset]. Which columns hold location and date?" |
Preview the data | "Show 10 sample rows from [dataset], only the date and location columns." |
Check data quality | "Check a sample of [dataset] for missing values or odd dates." |
Confirm access | "Can I download [dataset], or only sample it?" |
Plan your analysis
The MCP doesn't run queries, but it knows each dataset's columns, types, date partitions, size, and join keys. Your AI tool can use that to write code you run for downloading and running analyses.
Task | Example prompt |
|---|---|
Plan a download | "How big is [dataset], and should I download it in full or customize it first?" |
Write download code | "Write the Dewey Client command to download only 2024 from [dataset]." |
Filter and aggregate | "Write DuckDB SQL to count [dataset] records by state and month." |
Join tables | "Write code to join [dataset] with its companion tables on their join keys." |
Draft a codebook | "Draft a codebook for the [dataset] columns I plan to use." |
Cite the data | "Write a citation and data availability statement for [dataset]." |
⚙️ Worked Example: Exploring LinkUp Job Records data
Note: responses are shortened, and will vary. This example is to showcase an example workflow and possible uses of the MCP connection using LinkUp Job Records.
Step 1. Discover: search by topic
Prompt: "Find LinkUp job postings data I can use."
Example response: LinkUp Job Records (Company Insights, global), one row per job posting, plus companion tables such as Job Descriptions, Structured Fields, Extracted Salary, and Remote Tag.
Step 2. Evaluate: review the details
Prompt: "Tell me about Job Records: coverage, refresh schedule, and size."
Example response: Job postings scraped from employer websites worldwide, one row per posting. Refreshed monthly on the 6th. About 362 million rows (52.21 GB, Parquet).
Step 3. Evaluate: review the schema
Prompt: "Which columns hold location and date?"
Example response: Location:
CITY,STATE,ZIP, andCOUNTRY;UNMAPPED_LOCATIONflags postings whose location couldn't be identified. Date:CREATED, the first time LinkUp saw the posting, which the data is partitioned on.
Step 4. Evaluate: preview the data
Prompt: "Show 4 sample rows with title, city, state, country, and date."
Example response: Cities are in title case, US states are two-letter codes, and countries are three-letter codes:
title | city | state | country | created |
|---|---|---|---|---|
Lead Excavator Operator | Nashville | TN | USA | 2026-08-12 |
Real Estate Leasing Specialist | Dublin | OH | USA | 2026-10-08 |
Licensed Mental Health Therapist | Richmond | VA | USA | 2026-06-17 |
Assistenzarzt Unfallchirurgie | Freudenberg | North Rhine-Westphalia | DEU | 2025-08-27 |
Step 5. Evaluate: check data quality
Prompt: "Anything I should watch for before counting postings?"
Example response: The data is global, so filter
COUNTRY = 'USA'. A posting with several locations becomes several rows (sameBASE_HASH, differentJOB_HASH), so countBASE_HASHfor unique postings. Missing states can appear as the text "None". AndCREATEDis when LinkUp first saw the posting; the employer's posted date is in Structured Fields.
Step 6. Evaluate: confirm access
Prompt: "Can I download it?"
Example response: Yes. It's included in your subscription and doesn't require customization, but filtering first keeps the download far smaller than 52 GB.
Step 7. Plan: join tables
Prompt: "What companion tables come with Job Records, and how do they join?"
Example response: Eight, including Job Descriptions, Extracted Salary, Remote Tag, Skills, and ONET Taxonomy. Job Descriptions and Extracted Salary join on
JOB_HASH; company reference data joins onCOMPANY_ID.
Step 8. Plan: write download code
Prompt: "Write the code to get February 2026 job postings for Houston, TX."
Example response: three steps.
In Dewey, add Job Records to a Project. To shrink the download, customize it first (country USA, state TX, city Houston). City filters match any value containing your text, so step 3 narrows to exact matches.
Download February 2026 only (the Dewey Client reads
DEWEY_API_KEYautomatically):
python -m deweypy speedy-download prj_YOUR_PROJECT_ID \
  --partition-key-after 2026-02-01 --partition-key-before 2026-02-28
Filter to Houston with DuckDB:
SELECT *
FROM read_parquet('dewey-downloads/**/*.parquet')
WHERE COUNTRY = 'USA'
  AND STATE = 'TX'
  AND CITY = 'Houston'
  AND CREATED >= TIMESTAMP '2026-02-01'
  AND CREATED <  TIMESTAMP '2026-03-01';
Step 9. Plan: cite the data
Prompt: "How should I cite this dataset?"
Example response: LinkUp. (2025). Job Records (Version 1.3) [Data set]. Dewey Data. https://doi.org/10.82551/D6Q4-3W96
Note: Before you run AI-written code
Dewey doesn't run or check this code. Review it and test on a small download first.
Ask the AI to check value formats in a sample before filtering (here, cities are title case and countries are three-letter codes).
Ask what a column means before relying on it. Here,
CREATEDis when LinkUp first saw the posting, not the employer's posted date.Decide your geography: the city "Houston" is not the same as the Houston metro area.
❓Troubleshooting
Fixes for common setup and usage issues.
Problem | Fix |
|---|---|
Security | Always store your API Key as an environment variable. Never hardcode it in config files or commit it to source control. |
Dewey tools don't appear | Quit and reopen your AI tool. In CLI tools, type |
Authentication error | Check |
You issued a new API key | Update |
ChatGPT says the app is disabled | Ask your workspace admin to enable Dewey. |
Dewey disconnects in Claude | Reconnect in Settings > Connectors. |
A dataset is missing | Results only include datasets your account can access. Ask your librarian about your subscription. |
The AI doesn't use Dewey | Start with "Search Dewey for...". In Claude, check Dewey is on in the + menu. |
What the MCP doesn't do
Plan for these steps outside the MCP.
Download data. See Data Access for details on downloading.
Query, filter, or aggregate full datasets. It returns metadata and sample rows only, but you can use that to write or inform code to then use for downloading and analyses.
Change your account, Projects, or access.
Show datasets outside your access.
Still stuck? Email [email protected] with your AI tool and the error message.